Multimodal language model
Mary MLLM
Teaching a small language model to see, with a vision encoder and a two-layer bridge.
- 169
- image tokens per image
- 0.5B
- language model
- 2
- training stages
Overview
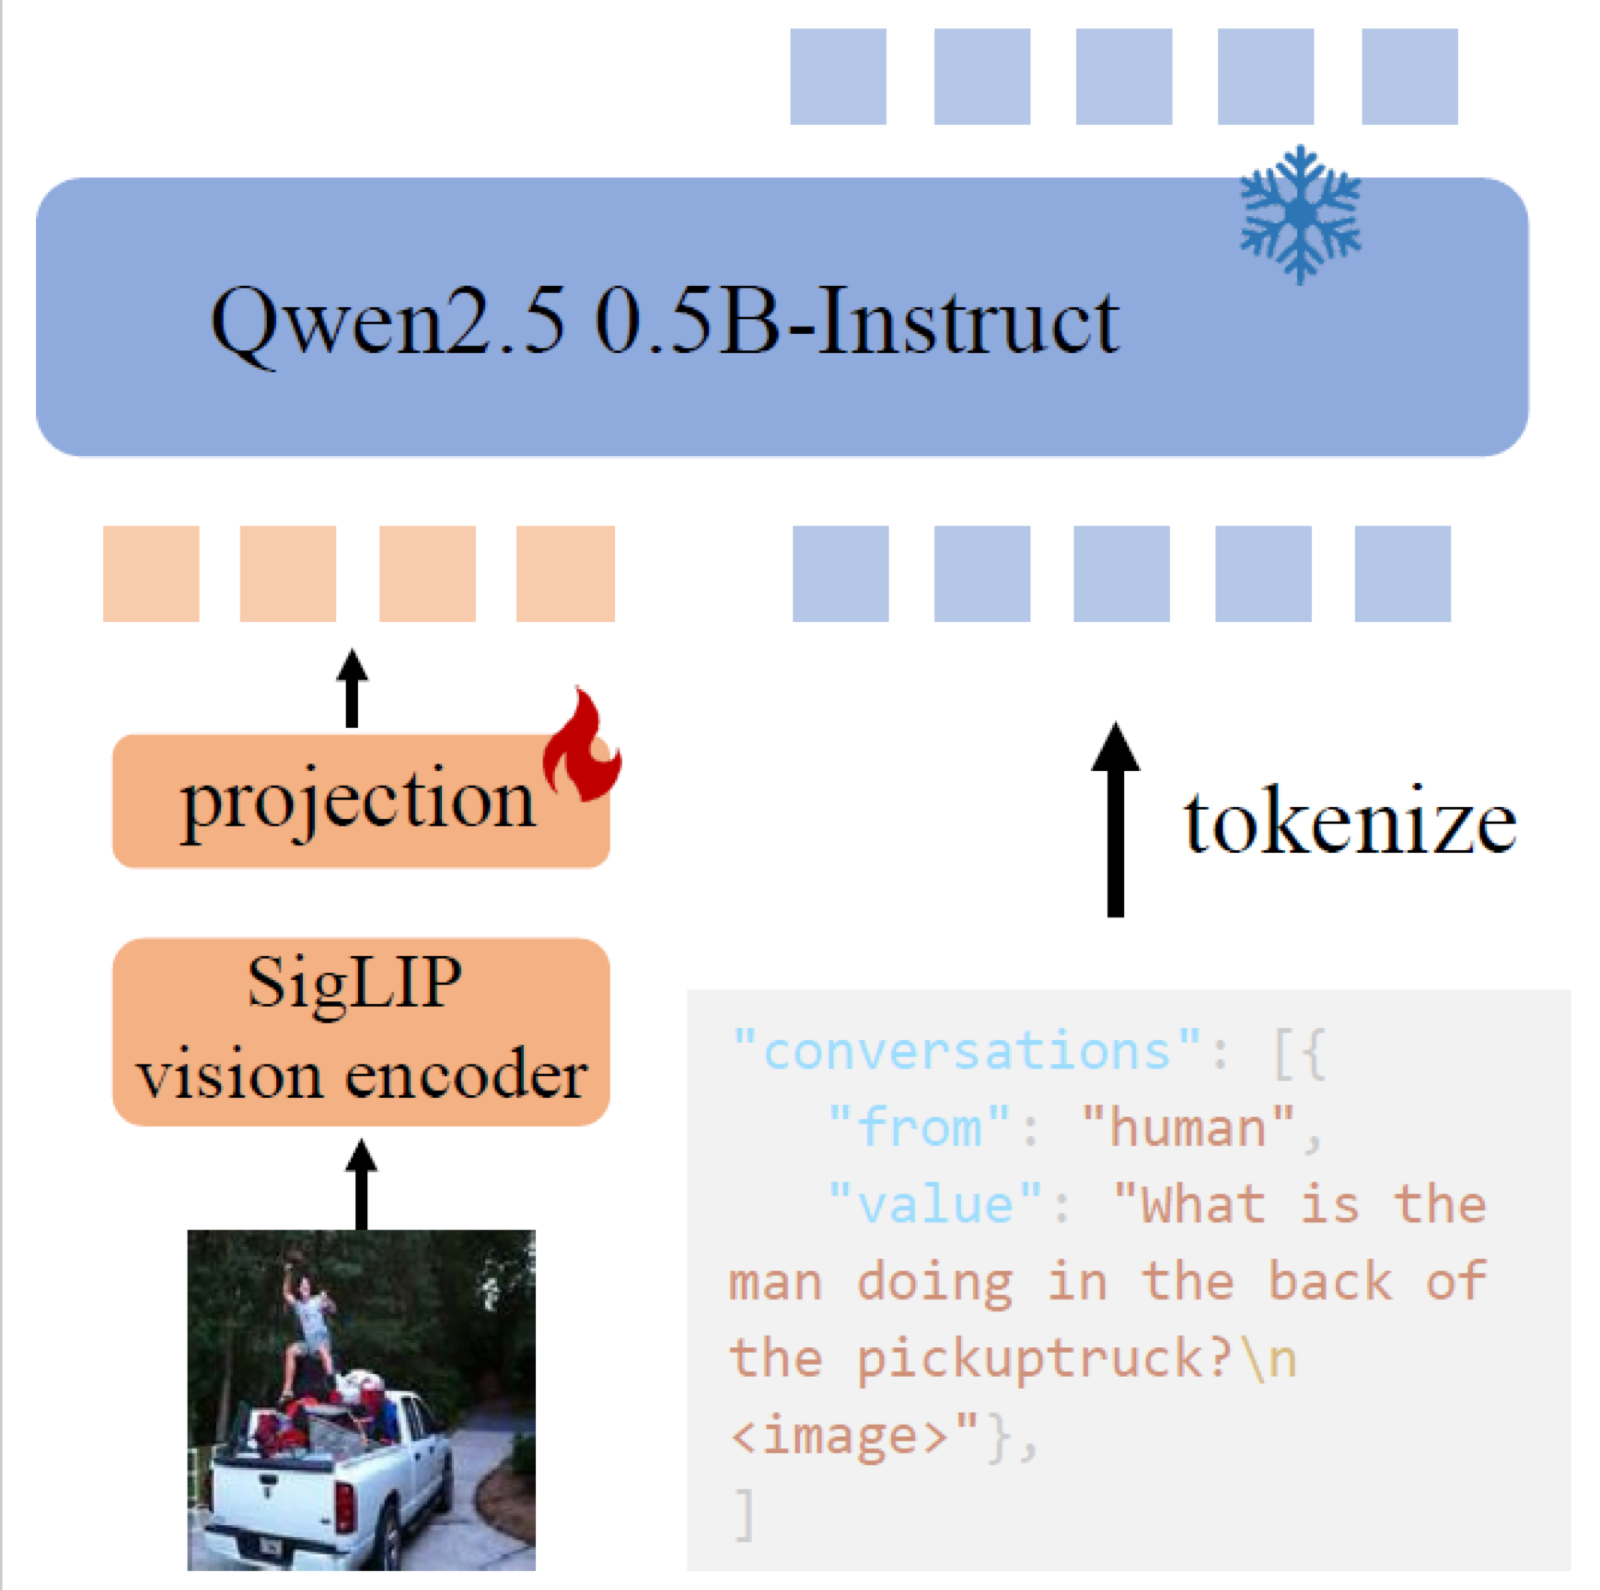
Mary MLLM connects an existing vision encoder to an existing small instruction-tuned language model, and trains only the connection between them. The language model never sees pixels — it sees a short sequence of tokens produced from the image, in the same embedding space as its words.
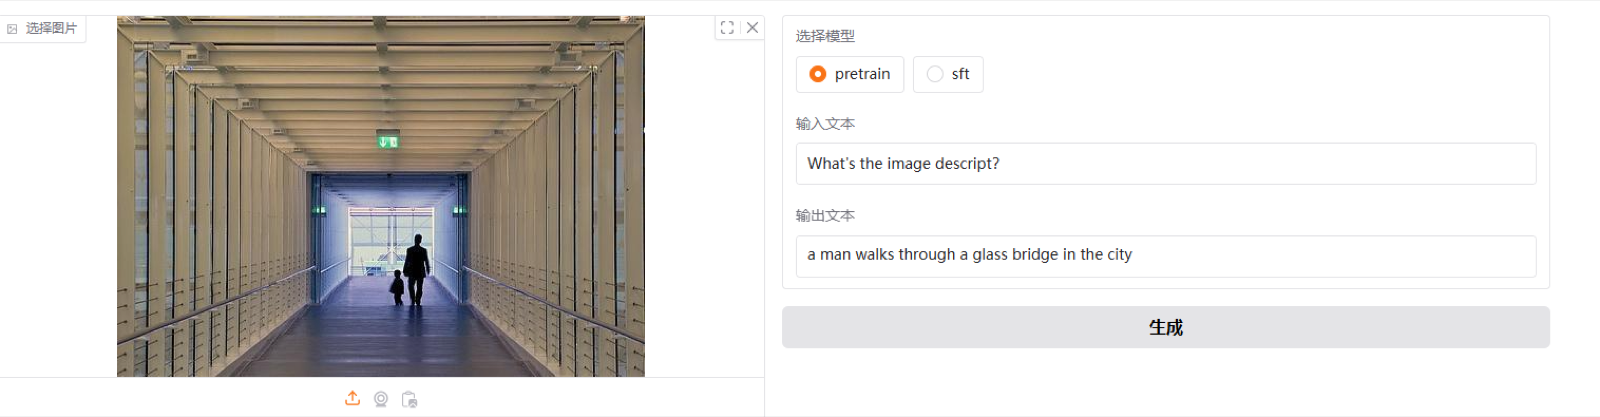
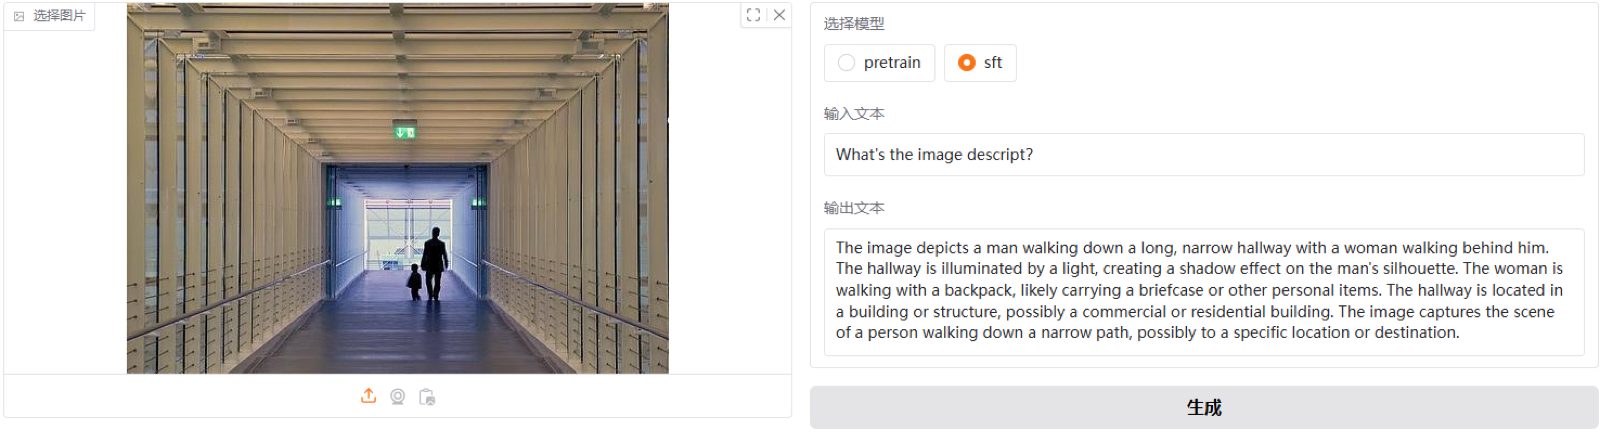
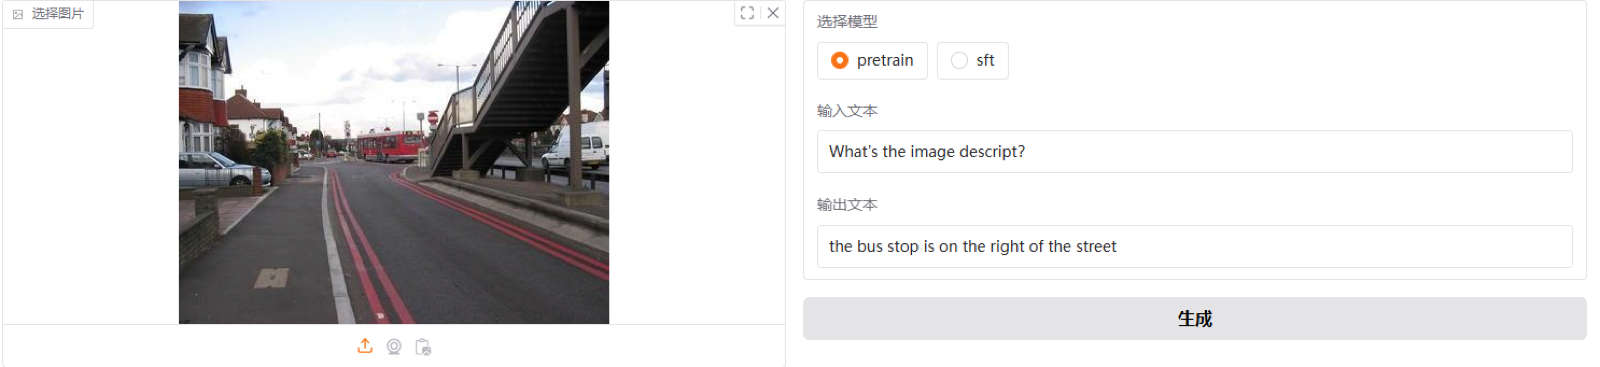
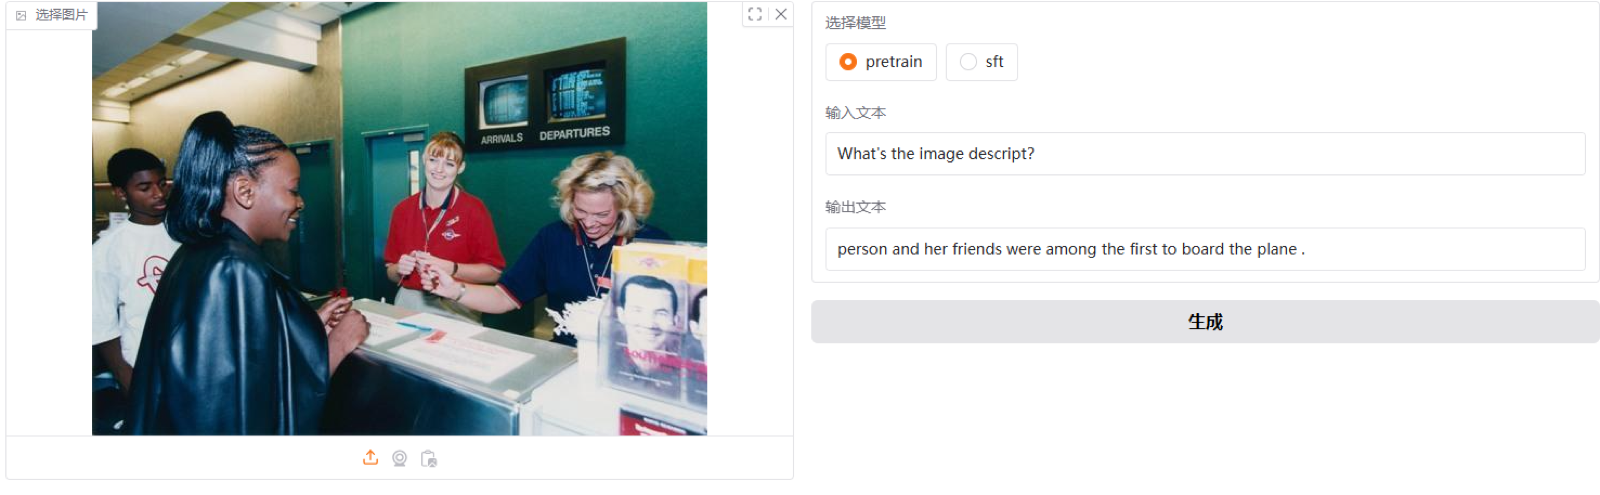
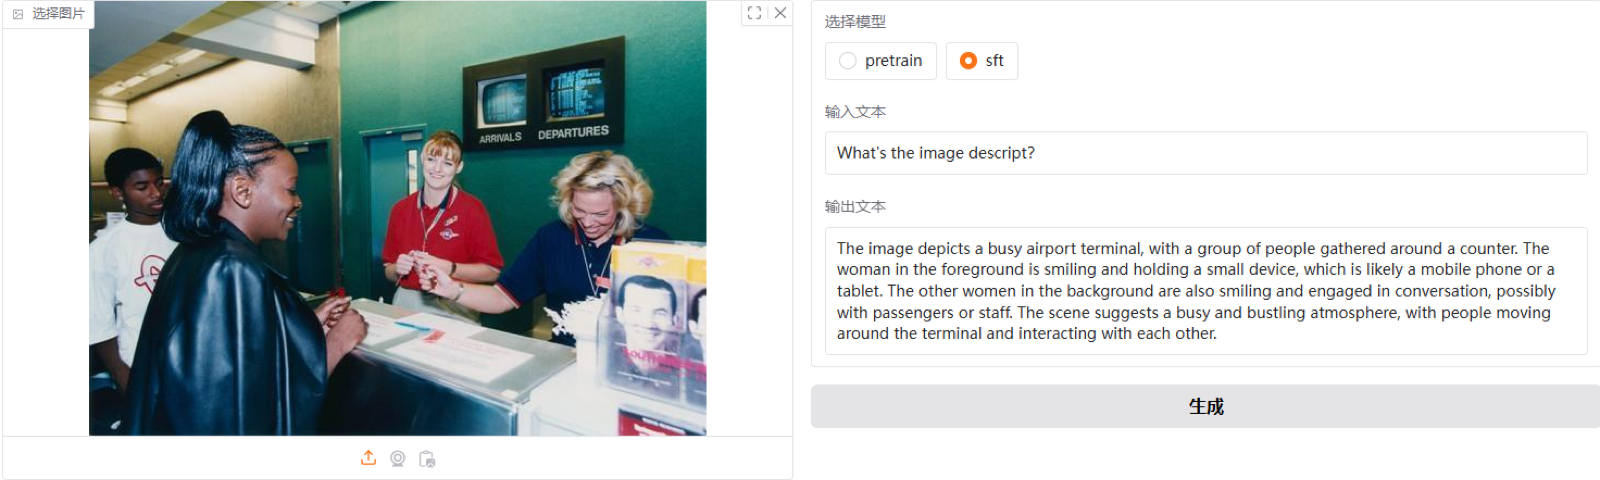
Training happens in two stages: first captions to teach the bridge to align images with language, then instruction data so the answers become detailed rather than one-line captions. The qualitative comparisons below show that shift, and also where a 0.5B model still falls short.
Components
- SigLIP (so400m, patch14, 384px)
- The vision encoder. It is trained to put images and their captions close together in one space, so its output already carries language-aligned meaning rather than raw pixels.
- Qwen2.5-0.5B-Instruct
- The language model — small enough to train on consumer GPUs, and already instruction-tuned, so it can follow a question once it can read the image.
- MLP projector
- A 2-layer network that maps downsampled vision features into 169 image tokens shaped like word embeddings. This is the only bridge between the two models.
- DeepSpeed
- Training framework used to fit the two-stage runs onto 4 × RTX 3090.
Architecture
Training stages
- 01
Pre-training on captions
LLaVA-CC3M-Pretrain-595K. Aligns the projector output with the language model's embeddings; answers stay short.
- 02
Instruction fine-tuning
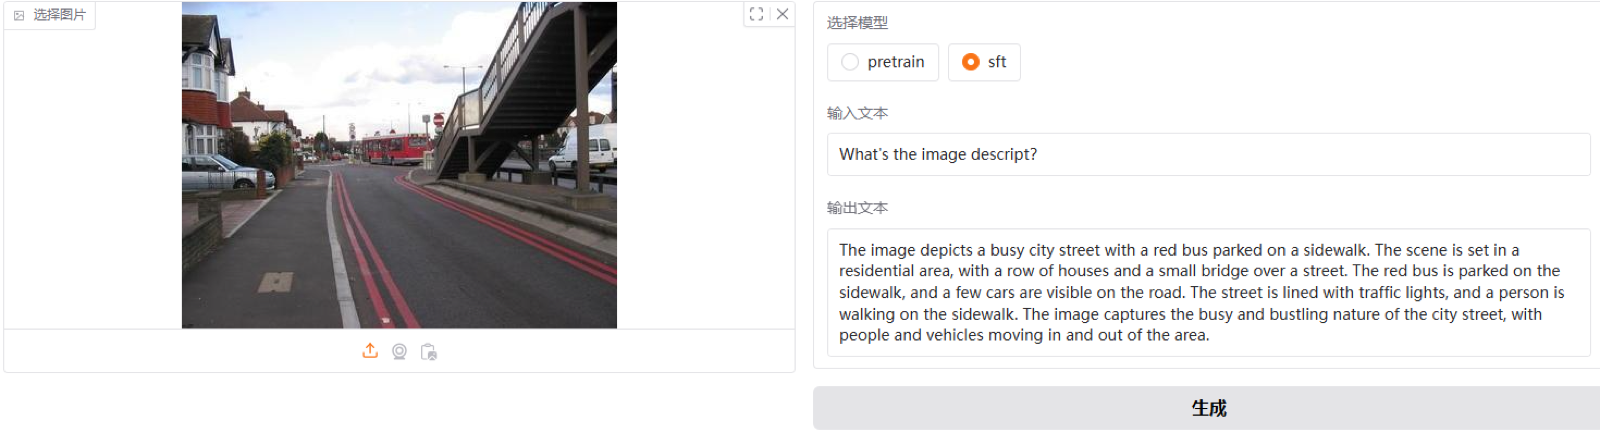
LLaVA-Instruct-150K. Teaches the model to answer questions about the image instead of naming what is in it.
Pre-train vs. SFT
Same image, same prompt, before and after the instruction stage.
Training environment
- Hardware
- RTX 3090 × 4
- Data
- LLaVA-CC3M-Pretrain-595K · LLaVA-Instruct-150K